COPUS: Co-adaptive Parallelism and Batch Size Selection in Large Language Model Training
Jointly adapting batch size and parallelism to improve useful training progress per unit of time.
Machine learning systems
I’m a Research Engineer at MBZUAI,
working on ML systems.
My main focus is cross-vendor mismatches between AMD and NVIDIA GPU platforms.
I started by working on language model architectures and training objectives, keeping their systems implications in mind. Through that work, I found myself most drawn to the systems questions: how we organize computation, use memory, and make training more efficient.
Those questions now guide my ML systems research. I’m looking for PhD opportunities in ML systems, bringing a perspective shaped by my work on language models and GPU platforms.
Understanding and addressing mismatches between AMD and NVIDIA GPU platforms.
Distributed training, parallelism, and using compute more effectively as models scale.
Understanding how training algorithms and system configurations interact, and designing them together.
Jointly adapting batch size and parallelism to improve useful training progress per unit of time.
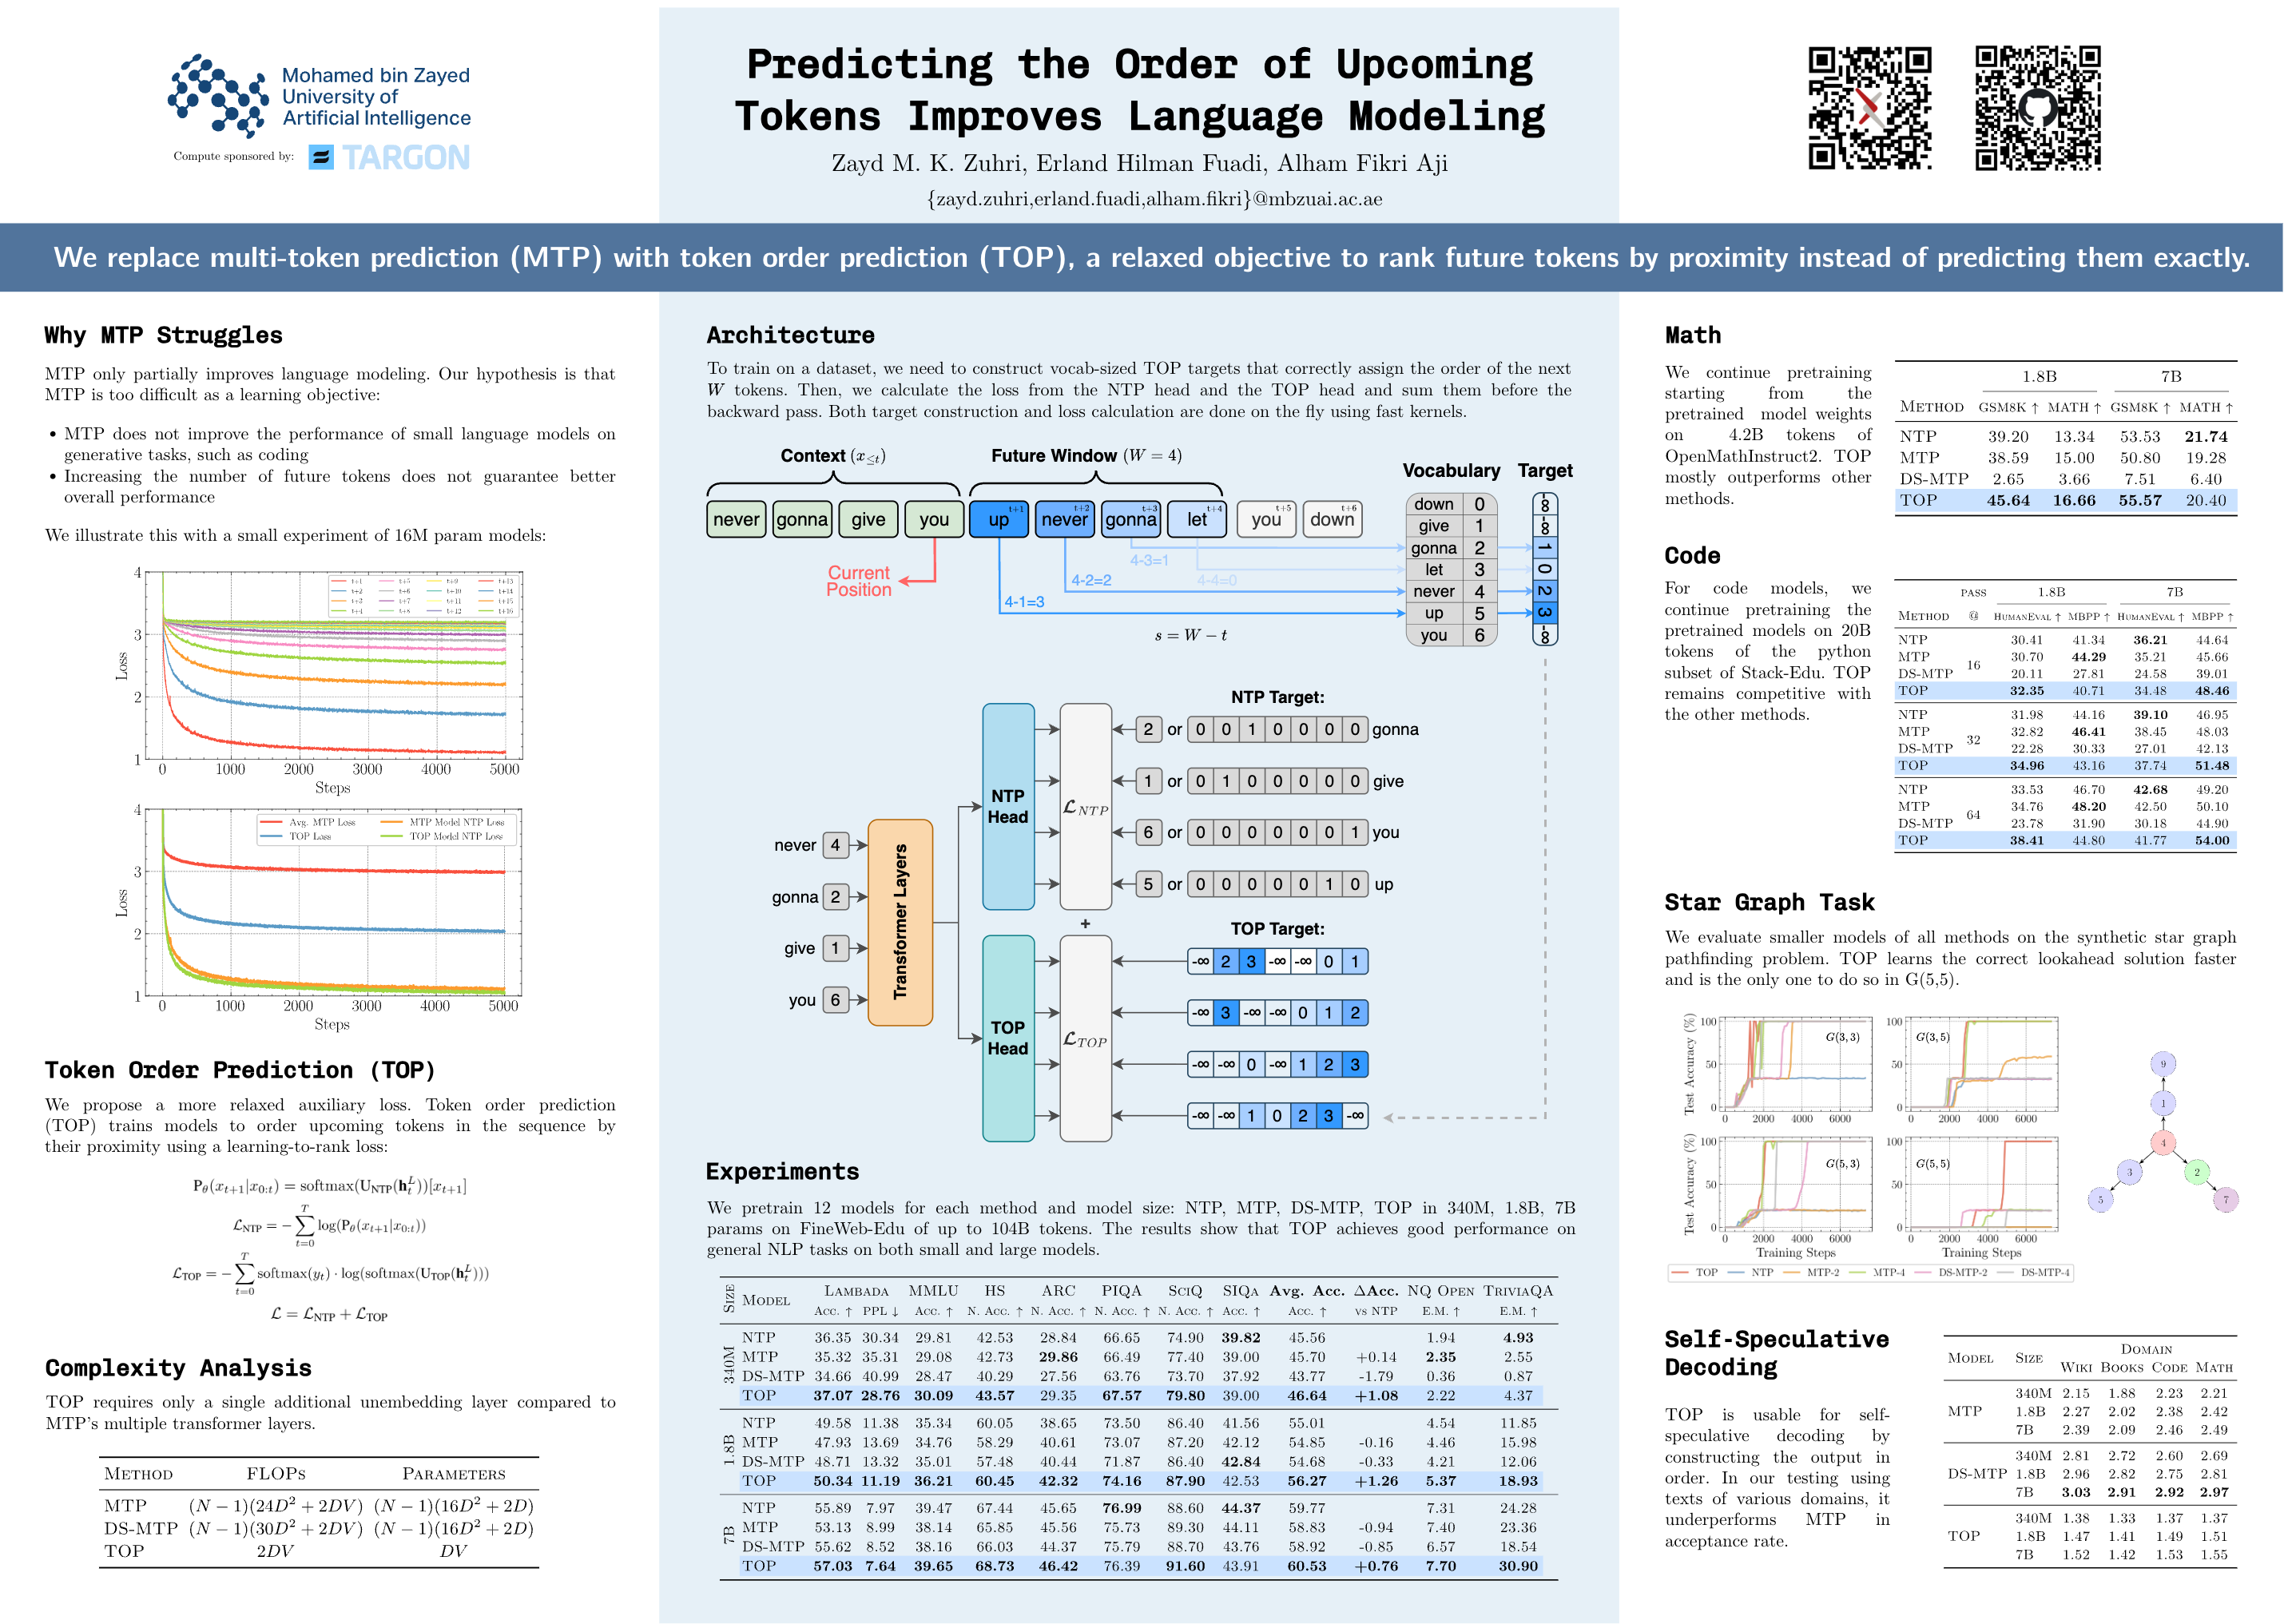
An auxiliary training objective that learns the relative order of future tokens using a ranking loss.
Rethinking attention normalization to eliminate attention sinks and massive activations, with implications for quantization and sparsity.
Evaluating commonsense reasoning grounded in Indonesian culture, in both standard and colloquial Indonesian.
Notes on ML systems, efficient training, and the systems questions behind language model research. First posts coming soon.